Machine Learning & Signals Learning
24 Image Segmentation
The image notation of Ch. 23 carries over: an input image \(\bX \in \mathbb {R}^{H\times W\times C_{\text {in}}}\), and \(C\) foreground classes.
Throughout this chapter:
-
• \(\bM \in \{0,1,\ldots ,C\}^{H\times W}\) is the ground-truth label map,
-
• \(\hat \bM = f_\theta (\bX )\) the predicted label map, and
-
• \(|\cdot |\) denotes pixel count.
Data augmentation (Sec. 23.4) carries over with one change: every geometric transformation applied to \(\bX \) is applied identically to the label map \(\bM \), so that each pixel keeps its label; photometric transformations leave \(\bM \) unchanged.
24.1 Background and foreground
One class index is reserved for the background (\(c=0\)): pixels that do not belong to any object of interest (sky, empty tissue, unlabelled regions). All other classes (\(c=1,\dots ,C\)) are foreground classes (tumour, road, vehicle, sheep), so \(C\) counts the foreground classes only and the total number of class indices is \(C+1\).
In a binary problem (\(C=1\)) there is a single foreground class and \(y_i\in \{0,1\}\) indicates whether pixel \(i\) belongs to it. With multiple foreground classes, each is treated separately when computing per-class losses and metrics: class \(c\) is its own foreground (\(y_i^{(c)}=1\)) and every other label, including the background (one-vs-rest), is its background (\(y_i^{(c)}=0\)). Foreground classes are typically the minority, and the pixel fraction each one occupies drives most of the design choices below (loss, metrics, sampling).
24.2 Objectives
Image segmentation comes in three flavors, distinguished by what each pixel of the output carries. It is useful to split classes into
-
• stuff (uncountable regions: sky, road, grass) and
-
• things (countable objects: sheep, car, person).
The corresponding objectives are:
-
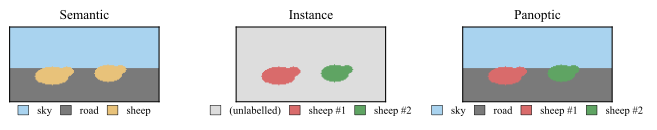
• Semantic segmentation: every pixel gets a single class label \(c\in \{0,\dots ,C\}\). Two sheep standing side by side are merged into one connected sheep region; the model cannot tell them apart.
-
• Instance segmentation: every thing pixel gets a pair (class, instance id), so the two sheep receive different ids; stuff pixels (sky, road) are left unlabelled.
-
• Panoptic segmentation: every pixel gets a pair (class, instance id). Things receive a unique id per object; each stuff class shares one id. It is a strict superset of the two above.
-
Example 24.1 (Two sheep on a road): Consider a \(2\times 4\) toy image (see also Fig. 24.1) with sky in the top row, road in the bottom row, and two sheep occupying the bottom-left and bottom-right pixels. Let class indices be \(\texttt {sky}=0\), \(\texttt {road}=1\), \(\texttt {sheep}=2\). The three flavors produce
\[ \underbrace {\begin {pmatrix}0&0&0&0\\2&1&1&2\end {pmatrix}}_{\text {semantic}},\quad \underbrace {\begin {pmatrix}\varnothing &\varnothing &\varnothing &\varnothing \\(2,1)&\varnothing &\varnothing &(2,2)\end {pmatrix}}_{\text {instance}},\quad \underbrace {\begin {pmatrix}(0,1)&(0,1)&(0,1)&(0,1)\\(2,1)&(1,1)&(1,1)&(2,2)\end {pmatrix}}_{\text {panoptic}} . \]
Semantic loses the count (one sheep region or two cannot be recovered from the label map); instance recovers the count but ignores sky and road; panoptic labels every pixel and distinguishes the two sheep.
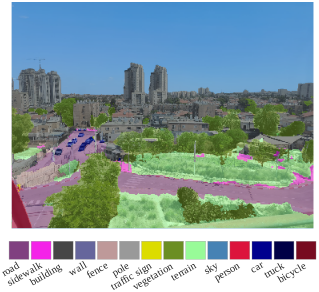
Note, per-pixel annotation is expensive.
Counter-indications for segmentation:
-
• If a single image-level label suffices, use a classifier that cheaper to label, train and run (Ch. 23).
-
• If approximate locations of multiple objects are enough, use detection (Ch. 25).
24.3 Benchmark datasets
Throughout this chapter and the next, metric conventions are tied to the public benchmarks that introduced them. The three datasets below cover detection, instance/panoptic segmentation, and urban-scene semantic segmentation; ImageNet, used in classification, is covered separately in Sec. 22.2.3.
Pascal VOC The PASCAL Visual Object Classes challenge ran from 2005 to 2012 and was the first widely-adopted detection/segmentation benchmark. The standard VOC2007 / VOC2012 splits contain \(\sim 11{,}000\) images annotated with \(20\) object classes (person, vehicles, animals, indoor objects) plus a background class. VOC introduced two conventions that this chapter inherits: the lenient IoU threshold \(\tau =0.5\) for box matching (Sec. 25.2) and 11-point interpolated AP for the pre-2010 editions, replaced by all-point interpolation from 2010 onward. VOC numbers are not directly comparable to COCO numbers because the threshold and interpolation conventions differ.
COCO Common Objects in Context (Lin et al., 2014) is the de-facto modern benchmark for detection, instance segmentation and panoptic segmentation. It contains \(\sim 330{,}000\) images with \(80\) “thing” classes (animals, vehicles, people, household objects) for detection / instance segmentation and a further \(91\) “stuff” classes (sky, road, grass) used by the panoptic split. COCO introduced the stricter mAP@[.5:.95] convention (averaging over ten IoU thresholds, Eq. 25.4), the \(\text {AP}_{\text {small/medium/large}}\) size breakdown that exposes the small-object weakness of IoU, and the mask-AP variant that reuses the detection recipe with mask IoU. Most pretrained detection/segmentation checkpoints in this chapter are trained on COCO.
Cityscapes Cityscapes (Cordts et al., 2016) is the standard semantic-segmentation benchmark for urban driving: \(5{,}000\) images with fine pixel-level annotations and a further \(\sim 20{,}000\) with coarse annotations, drawn from 50 European cities, evaluated on \(19\) classes (road, sidewalk, car, pedestrian, sign, \(\ldots \)) plus a void / ignore label for ambiguous or out-of-vocabulary pixels. The void label is the convention to remember: it must be excluded from both numerator and denominator of every metric, otherwise mIoU is silently inflated.
24.4 Pixel Accuracy
Pixel-level confusion matrix A multi-class confusion matrix \(N\in \mathbb {N}^{(C+1)\times (C+1)}\) (the per-pixel analogue of the per-sample matrix of Sec. 17.6.1),
\(\seteqnumber{0}{24.}{0}\)\begin{equation} N_{cc'} \;=\; \sum _{i,j} \indFunc \!\left [M_{ij}=c\right ]\,\indFunc \!\left [\hat M_{ij}=c'\right ] , \end{equation}
counts how many pixels of true class \(c\) are predicted as \(c'\). Every per-pixel metric below is a simple function of \(N\).
Pixel accuracy Pixel accuracy is the diagonal sum normalized by total pixels,
\(\seteqnumber{0}{24.}{1}\)\begin{equation} \text {PA} \;=\; \frac {\sum _c N_{cc}}{\sum _{c,c'} N_{cc'}} , \label {eq-dlarch-pa} \end{equation}
treating each pixel as an equal-weight classification example.
Per-class pixel accuracy The per-class pixel accuracy is the fraction of class-\(c\) pixels recovered,
\(\seteqnumber{0}{24.}{2}\)\begin{equation} \text {PA}_c \;=\; \frac {N_{cc}}{\sum _{c'} N_{cc'}} \;=\; \frac {\text {TP}_c}{\text {TP}_c+\text {FN}_c} , \end{equation}
which is the recall on class \(c\). The denominator \(\sum _{c'} N_{cc'}\) is the row-\(c\) sum of the confusion matrix, i.e. the number of pixels whose true label is \(c\), counted across every predicted class \(c'\).
\(\seteqnumber{0}{24.}{3}\)\begin{equation} \text {mPA} \;=\; \frac {1}{C+1}\sum _c \text {PA}_c \;=\; \frac {1}{C+1}\sum _c \frac {N_{cc}}{\sum _{c'} N_{cc'}} \end{equation}
averages \(\text {PA}_c\) equally over the \(C+1\) classes (\(+1\) stands for the background class). It is the macro-averaged per-class recall (Sec. 17.6.2), less biased by class frequency than PA.
24.5 Intersection over Union
24.5.1 Definition
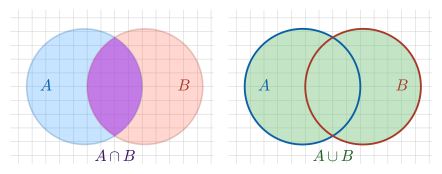
For two regions \(A\) and \(B\) (pixel sets, or, in Ch. 25, bounding boxes) the Intersection over Union (IoU, also called the Jaccard index) is
\(\seteqnumber{0}{24.}{4}\)\begin{equation} \text {IoU}(A,B) \;=\; \frac {|A\cap B|}{|A\cup B|} \;=\; \frac {|A\cap B|}{|A|+|B|-|A\cap B|} , \label {eq-dlarch-iou} \end{equation}
with \(\text {IoU}\in [0,1]\) (\(1\) for perfect overlap, \(0\) for disjoint regions).
Why IoU and not pixel accuracy? IoU penalises both false positives (predicted pixels outside the ground truth) and false negatives (ground-truth pixels missed). Pixel accuracy on a sparse foreground class can stay near \(1\) even when the model predicts everything as background; IoU collapses to \(0\) in that case.
24.5.2 IoU per class
For class \(c\), treating “class \(c\)” vs. “not class \(c\)” as a binary problem, apply the IoU definition (Eq. 24.5) with \(B=\{\,\text {pixels with } M_{ij}=c\,\}\) (the actual class-\(c\) region) and \(A=\{\,\text {pixels with } \hat M_{ij}=c\,\}\) (the predicted class-\(c\) region). The matrix entries read out the three set cardinalities directly:
-
• \(|A\cap B| = N_{cc} = \text {TP}_c\) — pixels that are class \(c\) in both the truth and the prediction (diagonal entry);
-
• \(|B| = \sum _{c'} N_{cc'} = \text {TP}_c + \text {FN}_c\) — row-\(c\) sum, all actual class-\(c\) pixels;
-
• \(|A| = \sum _{c'} N_{c'c} = \text {TP}_c + \text {FP}_c\) — column-\(c\) sum, all predicted class-\(c\) pixels.
-
• \(|A\cup B|=|A|+|B|-|A\cap B|\) - inclusion-exclusion formula.
Substituting into Eq. 24.5 gives
\(\seteqnumber{0}{24.}{5}\)\begin{equation} \text {IoU}_c \;=\; \frac {N_{cc}}{\sum _{c'} N_{cc'} + \sum _{c'} N_{c'c} - N_{cc}} \;=\; \frac {\text {TP}_c}{\text {TP}_c + \text {FP}_c + \text {FN}_c} . \end{equation}
24.5.3 Mean IoU
The mean IoU averages over classes,
\(\seteqnumber{0}{24.}{6}\)\begin{equation} \text {mIoU} \;=\; \frac {1}{C+1}\sum _{c=0}^{C} \text {IoU}_c , \label {eq-dlarch-miou} \end{equation}
and is the de-facto reporting metric. A frequency-weighted variant is
\(\seteqnumber{0}{24.}{7}\)\begin{equation} \text {fwIoU}=\sum _c f_c\,\text {IoU}_c \end{equation}
with \(f_c\) the pixel frequency of class \(c\) (the fraction of all pixels whose true label is \(c\)).
24.5.4 Median IoU
The median IoU is a robust alternative,
\(\seteqnumber{0}{24.}{8}\)\begin{equation} \text {medIoU} \;=\; \operatorname *{median}_{c=0,\dots ,C}\,\text {IoU}_c , \label {eq-dlarch-mediou} \end{equation}
useful on long-tailed benchmarks: a single rare class whose IoU collapses to near zero can drag mIoU down disproportionately, while medIoU is unaffected by such per-class outliers. It is sometimes reported alongside mIoU rather than instead of it.
What counts as a good (m)IoU? There is no universal cutoff, but on standard benchmarks:
-
• \(\text {mIoU}<0.5\): typically weak; usually a sign of class imbalance or that boundary errors dominate.
-
• \(0.5\)–\(0.7\): typical range for hard datasets.
-
• \(0.7\)–\(0.8\): strong; current SOTA.
-
• \(>0.9\): near-perfect, realistic only for easy or binary masks.
Per-class IoU varies widely within a single model: background and large classes routinely sit at \(0.9+\), while thin or rare classes (poles, pedestrians, lesions) often languish at \(0.3\)–\(0.5\) even for SOTA. This spread is why mIoU is always reported alongside per-class values.
24.6 Dice coefficient
The Dice coefficient (the \(F_1\) score in its binary form) is
\(\seteqnumber{0}{24.}{9}\)\begin{equation} \text {Dice}(A,B) \;=\; \frac {2|A\cap B|}{|A|+|B|} \;=\; \frac {2\,\text {TP}}{2\,\text {TP}+\text {FP}+\text {FN}} . \label {eq-dlarch-dice} \end{equation}
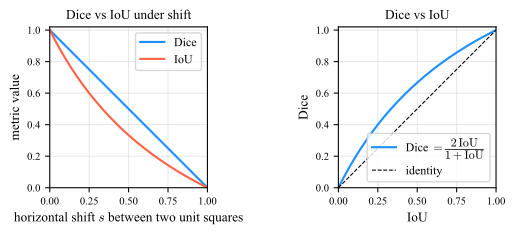
Dice and IoU are monotone transforms of each other,
\(\seteqnumber{0}{24.}{10}\)\begin{equation} \label {eq-dice-iou} \text {Dice} \;=\; \frac {2\,\text {IoU}}{1+\text {IoU}} , \qquad \text {IoU} \;=\; \frac {\text {Dice}}{2-\text {Dice}} , \end{equation}
so they rank methods identically; Dice gives a higher score for the same overlap (Fig. 24.5).
In medical imaging Dice is the dominant choice; in autonomous driving and general computer vision IoU is. The choice is conventional, so do not report both as if they were independent evidence.
On datasets where one class covers most pixels (typical for medical or satellite imagery) PA is misleading: predicting all-background scores near \(1\) in PA but \(0\) in mIoU. Always report mIoU or per-class IoU on imbalanced data.
-
Example 24.2 (Pixel metrics on a \(4\times 4\) image): A binary segmentation problem (foreground vs. background) on a \(4\times 4\) image. Ground truth \(\bM \) has the foreground (class \(1\)) in the top-left \(2\times 2\) block; the prediction \(\hat \bM \) has it shifted one pixel to the right:
\(M ={}\)
1100110000000000\(\hat M ={}\)
0110011000000000Cells are shaded by the class-\(1\) outcome: TP, FP, FN, TN. Compute pixel accuracy, and the IoU and Dice for each class.
-
Solution: For the foreground (class \(1\)) the per-pixel counts are \(\text {TP}=2\), \(\text {FP}=2\), \(\text {FN}=2\), \(\text {TN}=10\). Then
\(\seteqnumber{0}{24.}{11}\)\begin{align*} \text {PA} &= (2+10)/16 = 0.75 , \\ \text {IoU}_1 &= 2/(2+2+2) = 1/3 \approx 0.33 , \\ \text {Dice}_1 &= 2\cdot 2/(2\cdot 2+2+2) = 1/2 = 0.50 . \end{align*} For the background (class \(0\)) the roles swap: its \(\text {TP}_0=10\) are the class-\(1\) true negatives, while the class-\(1\) FP and FN become \(\text {FN}_0=2\) and \(\text {FP}_0=2\). Then
\(\seteqnumber{0}{24.}{11}\)\begin{align*} \text {IoU}_0 &= 10/(10+2+2) = 5/7 \approx 0.71 , \\ \text {Dice}_0 &= 2\cdot 10/(2\cdot 10+2+2) = 5/6 \approx 0.83 , \end{align*} so \(\text {mIoU}=(\text {IoU}_0+\text {IoU}_1)/2\approx 0.52\). PA looks reasonable, but IoU exposes that only one third of the foreground union is correctly predicted; the large background inflates both PA and the background’s own scores, which is why the foreground IoU (or mIoU) is the honest summary. Dice falls between PA and IoU as expected from (24.11).
24.7 Hausdorff distance
IoU and Dice score area overlap and are dominated by the interior of large objects, so a prediction can score well even while its boundary wanders far from the truth in a few places. The Hausdorff distance measures exactly that: the largest gap between the two boundaries (Fig. 24.6). It is the distance-based complement to the overlap metrics above and the standard companion to Dice in medical imaging, where contour carries clinical information (cf. the boundary metrics in Sec. 24.6). This distance exists in multiple variants.
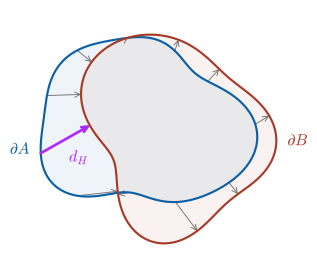
The Hausdorff distance is a length, not a ratio in \([0,1]\): it has no fixed scale and is comparable across results only at a fixed image resolution and voxel spacing.
24.8 Panoptic quality
Panoptic quality (PQ) grades a result at the level of whole segments rather than individual pixels. It is built in two stages, as follows.
Step 1: match segments Pair a predicted segment \(p\) with a ground-truth segment \(g\) only when their mask overlap clears \(\text {IoU}(p,g)>0.5\).
The threshold of 0.5 is what keeps the matching clean: no two predictions can both exceed \(0.5\) IoU with the same ground truth, so each ground truth matches at most one prediction and the pairing is unique. The matching sorts every segment into three counts (segment-level, not pixels):
-
• \(\text {TP}\) – matched pairs \((p,g)\);
-
• \(\text {FP}\) – predicted segments with no matching ground truth (spurious detections);
-
• \(\text {FN}\) – ground-truth segments with no matching prediction (misses).
Step 2: grade with two questions A good panoptic result must answer two independent questions, and PQ measures each with its own factor.
-
• Did the model find the right segments? This is recognition quality (RQ), the \(F_1\) score over segments, treating each segment as one classification example:
\(\seteqnumber{0}{24.}{11}\)\begin{equation*} \text {RQ} \;=\; \frac {|\text {TP}|}{|\text {TP}|+\tfrac 12|\text {FP}|+\tfrac 12|\text {FN}|} . \end{equation*}
The \(\tfrac 12\) weights split each unmatched segment evenly between FP and FN, the standard \(F_1\) form.
-
• When it does find a segment, how tightly does the mask fit? This is segmentation quality (SQ), the mean IoU over the matched pairs only (unmatched segments do not enter):
\(\seteqnumber{0}{24.}{11}\)\begin{equation*} \text {SQ} \;=\; \frac {\sum _{(p,g)\in \text {TP}}\text {IoU}(p,g)}{|\text {TP}|} . \end{equation*}
Step 3: combine Panoptic quality is the product of the two factors,
\(\seteqnumber{0}{24.}{11}\)\begin{equation} \text {PQ} \;=\; \underbrace {\frac {\sum _{(p,g)\in \text {TP}}\text {IoU}(p,g)}{|\text {TP}|}}_{\text {SQ}} \;\times \; \underbrace {\frac {|\text {TP}|}{|\text {TP}|+\tfrac 12|\text {FP}|+\tfrac 12|\text {FN}|}}_{\text {RQ}} . \label {eq-dlarch-pq} \end{equation}
Because it is a product, a high PQ demands both: detect the right segments (high RQ) and outline them tightly (high SQ). A model that detects everything with sloppy masks, or produces a few perfect masks while missing most objects, scores poorly.
-
Example 24.3 (Panoptic quality on a small image): A panoptic prediction returns four segments \(\hat I_1,\ldots ,\hat I_4\) on an image whose ground truth contains three segments \(I_1,I_2,I_3\). The pairwise mask IoUs between candidate pairs are
\[ \text {IoU}(\hat I_1,I_1)=0.82,\quad \text {IoU}(\hat I_2,I_2)=0.61,\quad \text {IoU}(\hat I_4,I_3)=0.34, \]
and all other pairs have IoU \(=0\). The matching at threshold \(0.5\) is shown in Fig. 24.7. Compute SQ, RQ and PQ.
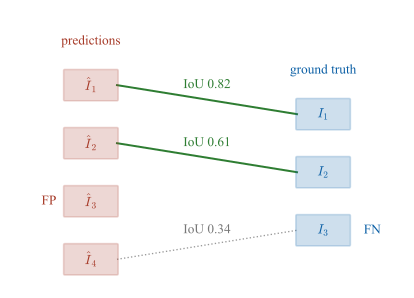 Figure 24.7: Matching predicted instances \(\hat I_k\) to ground-truth instances \(I_k\) by mask IoU at threshold \(0.5\). Solid green lines mark TP pairs (IoU above \(0.5\)); the dotted gray line is a below-threshold candidate that fails to match. Unmatched predictions become FP, unmatched ground truths become FN.
-
-
1. Match segments
Apply the \(0.5\) threshold. Only \((\hat I_1,I_1)\) at \(0.82\) and \((\hat I_2,I_2)\) at \(0.61\) clear \(\text {IoU}>0.5\), so they form the TP set; \((\hat I_4,I_3)\) at \(0.34\) does not match. Reading off the figure, the counts are
\[ |\text {TP}|=2 ,\qquad \underbrace {|\text {FP}|=2}_{\hat I_3,\,\hat I_4\ \text {unmatched}} ,\qquad \underbrace {|\text {FN}|=1}_{I_3\ \text {unmatched}} . \]
-
2. Grade with two questions
Recognition first, then mask fit:
\(\seteqnumber{0}{24.}{12}\)\begin{align*} \text {RQ} &= \frac {|\text {TP}|}{|\text {TP}|+\tfrac 12|\text {FP}|+\tfrac 12|\text {FN}|} = \frac {2}{2 + \tfrac 12\cdot 2 + \tfrac 12\cdot 1} = \frac {2}{3.5} \approx 0.571 , \\ \text {SQ} &= \frac {\text {IoU}(\hat I_1,I_1)+\text {IoU}(\hat I_2,I_2)}{|\text {TP}|} = \frac {0.82+0.61}{2} = 0.715 . \end{align*}
-
3. Combine
Multiply the two factors (Eq. 24.12),
\[ \text {PQ} = \text {SQ}\times \text {RQ} \approx 0.715\times 0.571 \approx 0.408 . \]
The matched masks overlap fairly well on average (SQ \(\approx 0.72\)), but two spurious predictions and a missed ground truth drag RQ down to \(0.57\), and the product punishes the model in both dimensions at once.
-
What counts as a good PQ? There is no universal cutoff, but on standard panoptic benchmarks:
-
• \(\text {PQ}<0.3\): typically weak; usually means many segments are unmatched or masks are loose.
-
• \(0.3\)–\(0.4\): typical range for hard datasets.
-
• \(0.4\)–\(0.55\): strong.
-
• \(0.55\)–\(0.65\): SOTA.
-
• \(>0.7\): near-perfect, realistic only for easy or binary cases.
Because \(\text {PQ}=\text {SQ}\times \text {RQ}\), a low PQ alone is ambiguous: report SQ and RQ separately to localise the problem (loose masks vs. poor detection).
24.9 Instance segmentation
Evaluation reuses the detection recipe of Sec. 25.2 below, with mask IoU (Eq. 24.5 applied to per-instance binary masks) replacing box IoU. The standard mask-AP metric is the COCO (Sec. 24.3) mAP averaged over IoU thresholds \(\{0.5,0.55,\ldots ,0.95\}\) (mAP@[.5:.95], Eq. 25.4) applied to masks instead of boxes.
Inference hyperparameters Two deployment-time knobs sit between the network output and the reported metric:
-
• Score threshold \(\tau _{\text {score}}\): the confidence below which predicted segments are dropped before any TP/FP/FN counting. For computing mAP, keep \(\tau _{\text {score}}\) low (e.g. \(0.05\)) so the precision–recall curve is sampled across the full operating range (Sec. 25.2). For visualisation or deployment, raise it (e.g. \(0.5\)–\(0.7\)) so only confident segments are shown.
-
• Mask threshold \(\tau _{\text {mask}}\): the per-pixel probability cutoff that binarises the soft mask into \(\{0,1\}\) at inference, \(\hat M_{ij} = \indFunc [p_{ij} > \tau _{\text {mask}}]\) (the same \(0.5\) choice that defines the hard-mask Dice loss in Sec. 24.6 below). Lower it to grow masks (boosts recall, may merge instances); raise it to shrink them (boosts precision, may fragment).
Both \(\tau _{\text {score}}\) and \(\tau _{\text {mask}}\) change the reported mask IoU and PQ even with the network frozen, because both metrics are computed on the binarised, score-filtered prediction. Reporting numbers without disclosing the two thresholds is a common reproducibility gap.
24.10 Dice Loss
24.10.1 Definition
The baseline is per-pixel cross-entropy summed over the \(H\times W\) grid, identical to a classification CE applied independently at every pixel. On imbalanced foreground (small lesions on large background, thin roads on large satellite tiles), CE alone underweights the minority class and the model collapses toward the background.
The Dice loss addresses this directly. In the binary case (background and foreground, \(C=1\)),
\(\seteqnumber{0}{24.}{12}\)\begin{equation} \mathcal {L}_{\text {Dice}} \;=\; 1 \;-\; \frac {2\sum _i p_i\,y_i}{\sum _i p_i + \sum _i y_i} , \end{equation}
where \(p_i\in [0,1]\) is the predicted foreground probability and \(y_i\in \{0,1\}\) the ground-truth indicator at pixel \(i\) (with \(i\) ranging over all \(HW\) pixels). Each of the three sums has a direct interpretation:
-
• \(\sum _i y_i = |B|\) counts the foreground pixels in the ground-truth mask,
-
• \(\sum _i p_i\) is the soft analogue of \(|A|\): the expected number of foreground pixels predicted by the model, where each pixel contributes its probability rather than a \(\{0,1\}\) vote, and
-
• \(\sum _i p_i\,y_i\) measures their soft overlap (the predicted probability summed over the true foreground pixels).
Two variants share this formula and differ only in the input.
-
• The soft Dice loss is \(\mathcal {L}_{\text {Dice}}\) as written above: the inputs are the continuous probabilities \(p_i\in [0,1]\), so the loss is differentiable in the model parameters and can drive training.
-
• The hard-mask Dice loss replaces \(p_i\) with the thresholded mask \(\hat p_i = \indFunc [p_i > 0.5]\in \{0,1\}\) before the same formula is evaluated; the three sums then become the cardinalities \(|B|\), \(|A|\) and \(|A\cap B|\), recovering the set-based Dice coefficient of Eq. 24.10 (Sec. 24.6). Training therefore uses the soft form (gradient everywhere); evaluation reports the hard form (matches the set-based coefficient that humans interpret).
24.10.2 Motivation (*)
Because Dice definition in 24.11 makes it a strictly increasing function of IoU, minimising \(\mathcal {L}_{\text {Dice}}\) is equivalent to maximising IoU: any drop in the loss is a guaranteed gain in IoU on the same prediction, so the loss and the evaluation metric rank predictions in the same order.
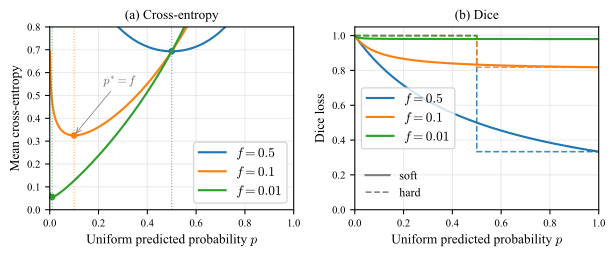
The second advantage is robustness to class imbalance. Let \(f = \tfrac {1}{HW}\sum _i y_i\) denote the foreground fraction (the share of pixels of foreground). For per-pixel cross-entropy with a constant-probability predictor \(p_i\equiv p\) (every pixel’s predicted foreground probability \(p_i\) is the same scalar \(p\), so the loss is a function of one number instead of \(HW\)), the optimum is \(p^*=f\): as \(f\to 0\), CE rewards the model for predicting all-background and the foreground gradient vanishes. Dice loss has no such collapse, because its ratio is scale-invariant in the foreground set: doubling \(\sum _i y_i\) and \(\sum _i p_i y_i\) together leaves \(\mathcal {L}_{\text {Dice}}\) unchanged, so a tiny foreground is not automatically a small loss. Figure 24.8 shows both behaviours side by side at three foreground fractions:
-
• \(f=0.5\) – balanced (a roughly 50/50 split, e.g. generic binary classification). The CE optimum sits at \(p^{*}=0.5\) (middle dotted line in panel a); CE and soft Dice agree on direction, both descending together as \(p\to 1\). The hard-mask Dice loss in panel b drops from \(1\) (all-background, \(p\le 0.5\)) to \((1-f)/(1+f)=1/3\) (all-foreground, \(p>0.5\)) – a clear improvement, though Dice\(=2/3\) is still far from a good prediction.
-
• \(f=0.1\) – mildly imbalanced (typical foreground objects in natural images). The CE optimum has slid left to \(p^{*}=0.1\): a model that admits only \(10\%\) foreground confidence is already CE-optimal, while soft Dice keeps decreasing all the way to \(p=1\) and its gradient still asks for more foreground confidence. Hard-mask Dice plateaus at \((1-f)/(1+f)\approx 0.82\) on \(p>0.5\).
-
• \(f=0.01\) – severely imbalanced (small lesions in medical scans, thin roads in satellite tiles). The CE optimum collapses against the left axis: predicting all-background is essentially optimal and the foreground gradient is negligible. Soft Dice is still monotone-decreasing in \(p\), but the hard-mask Dice loss only drops to \(\approx 0.98\) even after thresholding everything to foreground – which is why training uses the soft form rather than thresholding inside the loss.
-
Example 24.4 (Dice loss on three predictors): Take the \(4\times 4\) ground-truth mask of the pixel-metrics example (Example 24.2), foreground in the top-left \(2\times 2\) block (\(f=4/16=0.25\)). Compute the hard-mask Dice loss for three predictions: (A) all-background \(\hat M\equiv 0\); (B) the foreground shifted one pixel to the right (TP\(=\)FP\(=\)FN\(=2\)); (C) an exact match. For each, also report pixel accuracy (PA, Eq. 24.2, the share of correctly labelled pixels): does PA tell the degenerate predictor (A) apart from the partially-correct one (B), and does it agree with Dice on which prediction is worst?
-
Solution: With \(\text {Dice}=\tfrac {2\,\text {TP}}{2\,\text {TP}+\text {FP}+\text {FN}}\) and \(\mathcal {L}_{\text {Dice}}=1-\text {Dice}\):
\(\seteqnumber{0}{24.}{13}\)\begin{align*} \text {(A)}\quad & \text {TP}=0,\ \text {FP}=0,\ \text {FN}=4: && \mathcal {L}_{\text {Dice}} = 1 - 0/4 = 1, && \text {PA}=12/16=0.75, \\ \text {(B)}\quad & \text {TP}=2,\ \text {FP}=2,\ \text {FN}=2: && \mathcal {L}_{\text {Dice}} = 1 - 4/8 = 0.5, && \text {PA}=12/16=0.75, \\ \text {(C)}\quad & \text {TP}=4,\ \text {FP}=0,\ \text {FN}=0: && \mathcal {L}_{\text {Dice}} = 0, && \text {PA}=1. \end{align*} The degenerate all-background predictor (A) still scores \(\text {PA}=0.75\) because 12 of 16 pixels are background, yet \(\mathcal {L}_{\text {Dice}}=1\) flags it as the worst possible solution. (A) and (B) are indistinguishable to pixel accuracy but separated by \(0.5\) in Dice loss. This is precisely the imbalance regime where CE alone leaves the model stuck at (A); adding Dice to the loss restores a useful gradient.
Multi-class case. With \(C\) foreground classes and a softmax probability vector output \(\bp _i\in [0,1]^{C+1}\) at every pixel and the ground truth is the one-hot vector \(\by _i\). The Dice loss is computed per class against its one-vs-rest indicator and then averaged,
\(\seteqnumber{0}{24.}{13}\)\begin{equation} \mathcal {L}_{\text {Dice}}^{\text {multi}} \;=\; 1 \;-\; \frac {1}{C}\sum _{c=1}^{C}\frac {2\sum _i p_i^{(c)} y_i^{(c)}}{\sum _i p_i^{(c)} + \sum _i y_i^{(c)} + \varepsilon } , \end{equation}
where \(p_i^{(c)}\) is the softmax probability of class \(c\) at pixel \(i\), \(y_i^{(c)}\in \{0,1\}\) is the one-hot ground-truth indicator, and \(\varepsilon \) is a small constant (\(\sim 1\)) that prevents division by zero on images where a class is absent (\(\sum _i y_i^{(c)}=0\)). The background class \(c=0\) is excluded from the sum.
Practical recipe. The standard combined loss is \(\mathcal {L} = \mathcal {L}_{\text {CE}} + \mathcal {L}_{\text {Dice}}\) (binary or multi-class as appropriate), which keeps the per-pixel calibration of CE and the imbalance robustness of Dice.
24.10.3 Summary
-
• Evaluating segmentation on tiles that overlap training tiles. Large images (satellite scenes, histology slides, whole-slide MRI) do not fit in GPU memory and are cropped into smaller patches (tiles), often with deliberate overlap so objects on a tile boundary appear whole in some neighbouring tile. If train/test tiles are then drawn from the same source image (e.g. a random tile-level split), the test tiles share pixels with training tiles and the model has effectively memorised the answer for that region. The resulting IoU is dramatically inflated relative to performance on a truly unseen image. The fix is to split at the image level, not the tile level: all tiles from a given source image go to exactly one of train/val/test.
-
• Forgetting the void or ignore label (e.g. on Cityscapes, Sec. 24.3). Void pixels must be excluded from both numerator and denominator of every metric.
-
• Computing per-image mIoU and then averaging over images. The accepted convention is to accumulate the confusion matrix over the entire test set first and compute mIoU once.
Evaluate performance by mIoU on a held-out test set, accumulating the confusion matrix once over the whole set, and report per-class IoU on imbalanced data.
Further Reading
-
• Segment Anything and Segment Anything Model by Meta AI Demos (accessed 25-May-2026)
-
• Segment Anything by Hugging Face (accessed 25-May-2026)
-
• Conversational image segmentation with Gemini 2.5 by Google (accessed 25-May-2026)